Unified & Multimodal Models
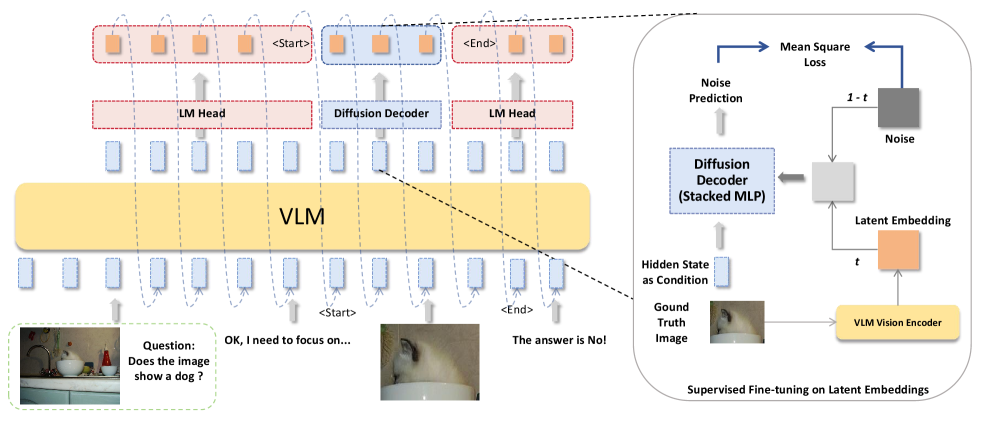
One backbone that jointly understands and generates across vision and language, closing the gap between perception and generation.
AI · Machine Learning · Reasoning
Building models that see, reason, and act — toward unified multimodal intelligence.
5 distinct publications · Citation metrics from Google Scholar · Updated
I'm an AI researcher focused on unified & multimodal models, large language / vision-language models, and reasoning & planning. My work asks how a single model can perceive across modalities, reason over long chains of thought, and plan actions in the world.
I'm currently a Research Scientist at Aether AI, which I joined in May 2026. I received my M.S. in Computer Science & Engineering from UC San Diego, where I worked with Zhiting Hu and Biwei Huang. I earlier completed my B.S. at the University of Electronic Science and Technology of China (UESTC).
Open to research collaboration, idea exchange, and paper discussions.
One backbone that jointly understands and generates across vision and language, closing the gap between perception and generation.
Eliciting long chain-of-thought and latent reasoning so models can plan, self-correct, and think before they act.
Learning predictive models of the world that let agents imagine, simulate, and act with foresight.
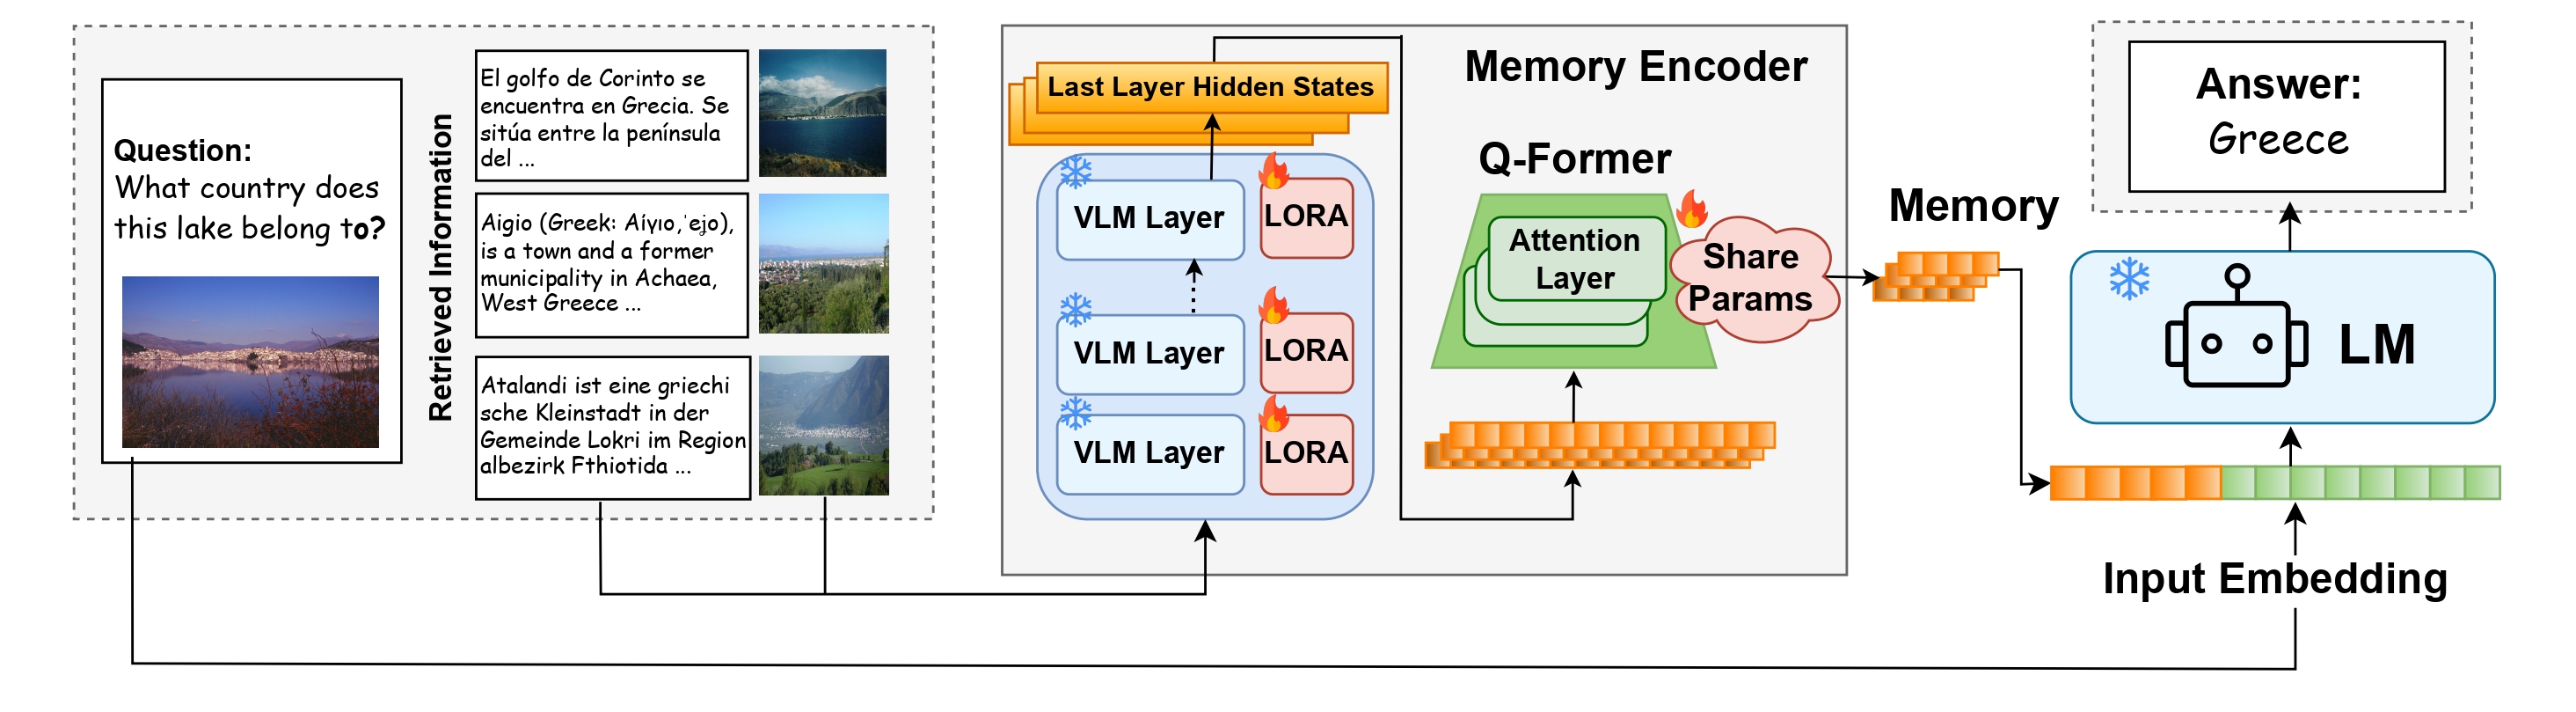
Making large models practical — activation control, memory, and inference systems that scale.
 NeurIPS 2025 · Spotlight
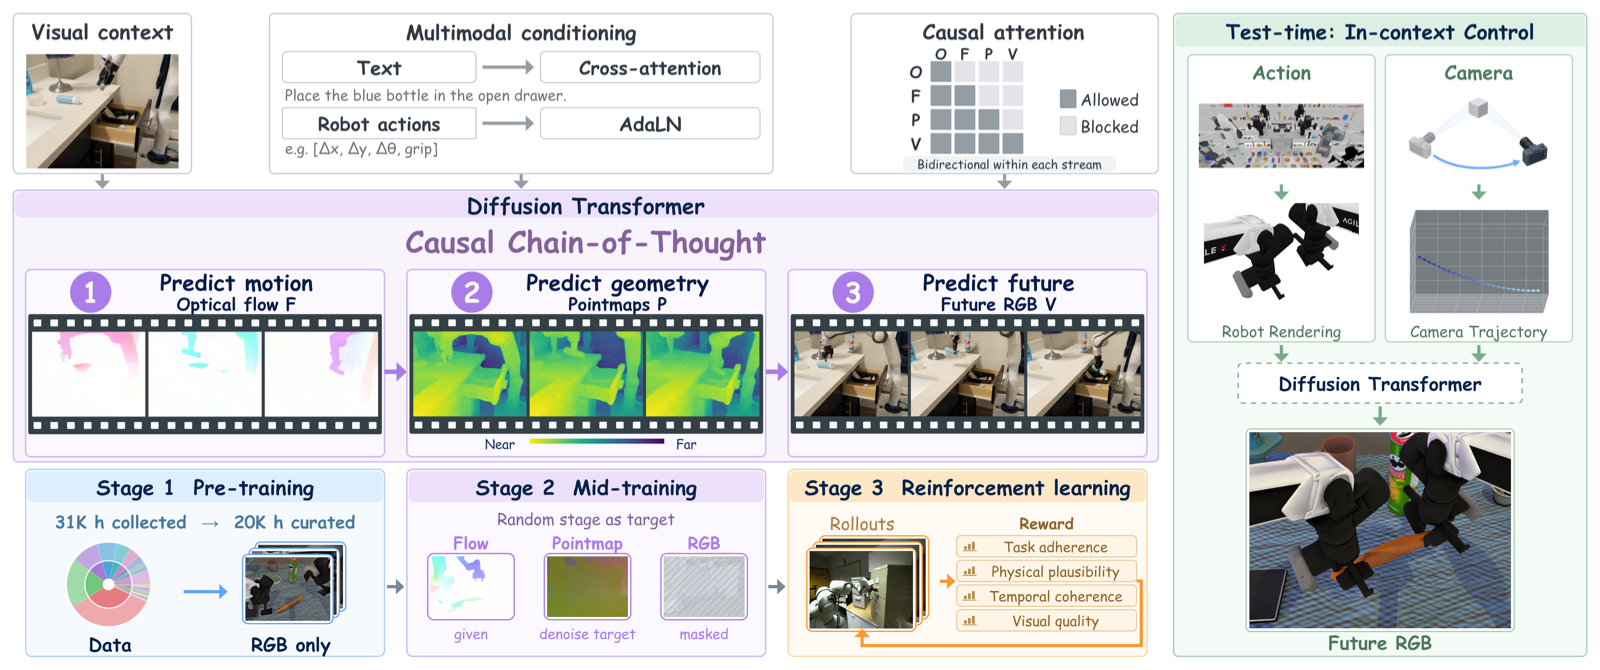
Released CausalWM, an embodied world model that reasons through motion and geometry before predicting future video. Explore the project ↗
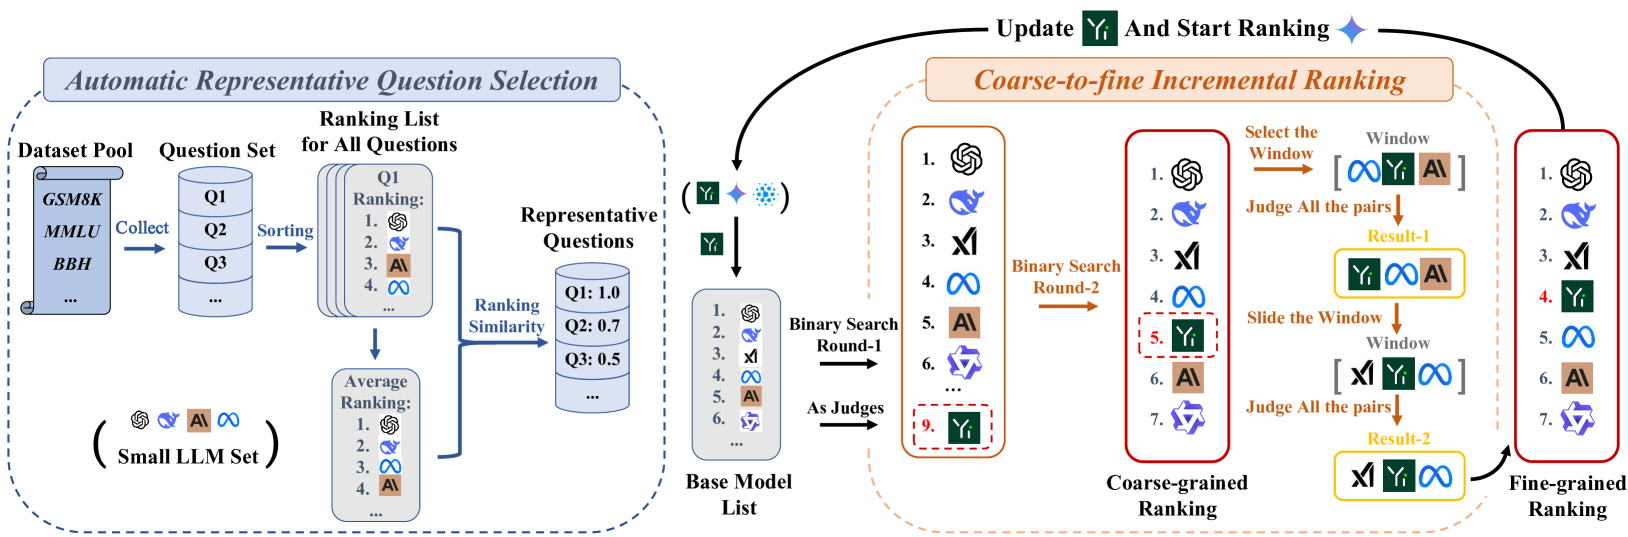
Two papers accepted — Decentralized Arena at ACL 2026 & new work on modal-mixed CoT reasoning.
Joined Aether AI as a Research Scientist, building the next generation of reasoning agents.
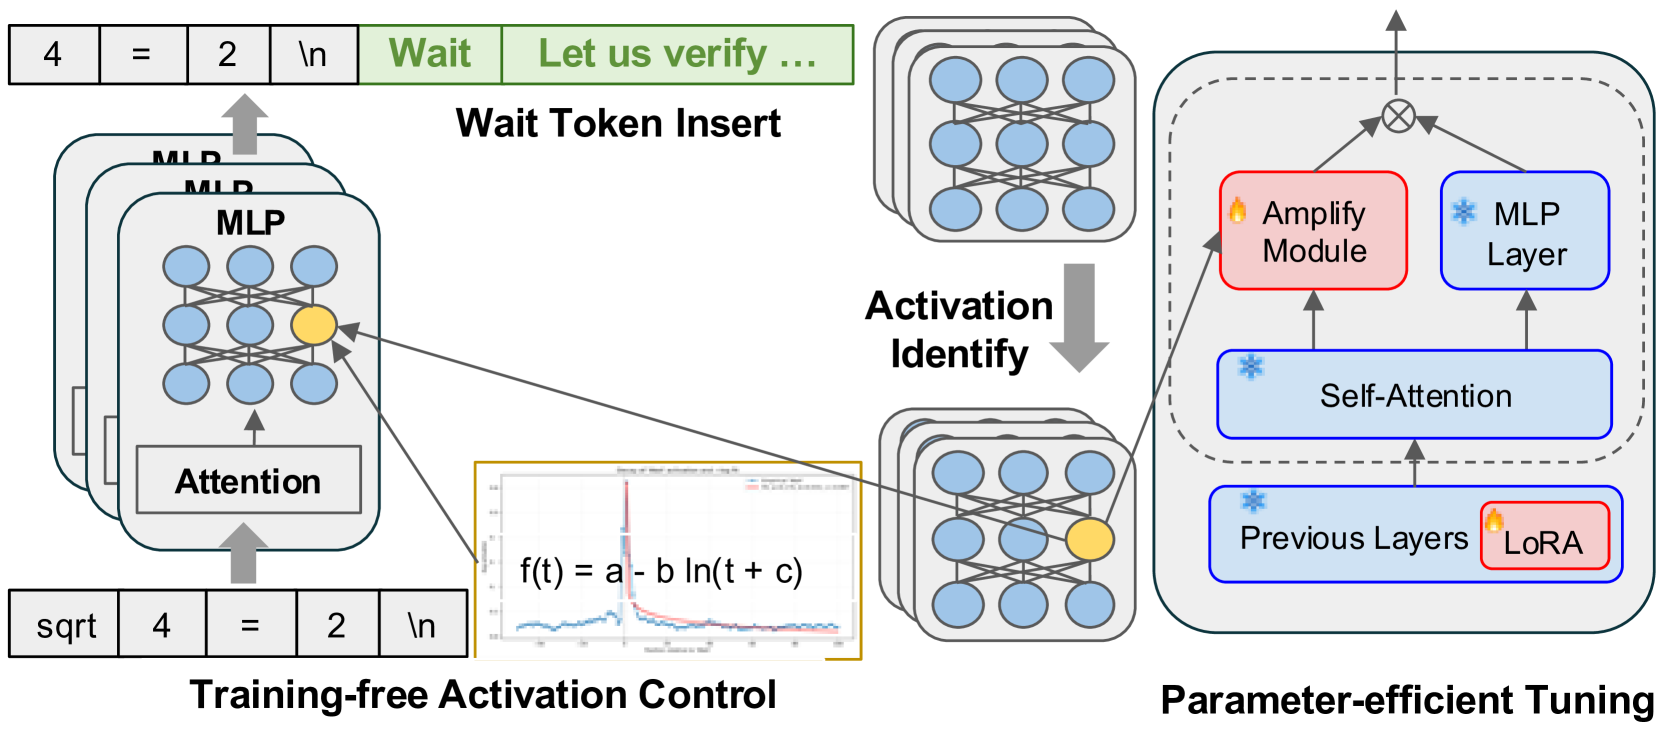
Two papers at NeurIPS 2025, including a Spotlight on activation control for long chain-of-thought.
Always happy to talk research, collaborations, or new ideas.